
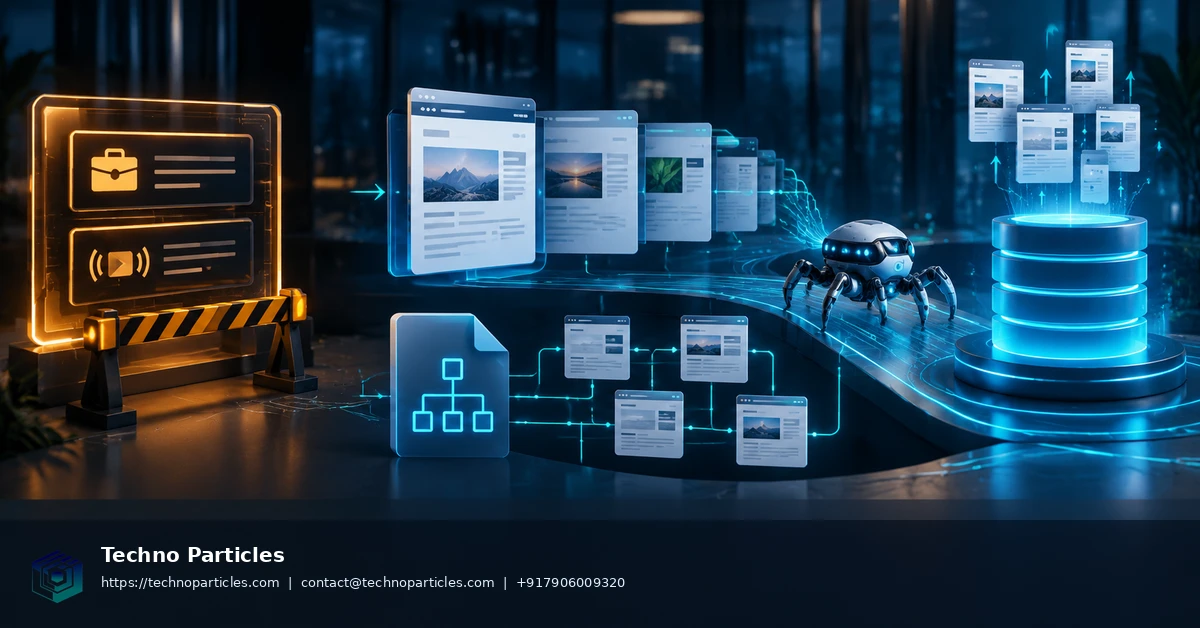
Google’s latest documentation update clarifies an important limitation for publishers trying to get ordinary new pages discovered faster. The Indexing API is not a general-purpose submission channel for blog posts, service pages, product pages or ecommerce content. Google’s quota documentation, updated October 16, 2026, lists current request limits, but does not expand the API’s supported page types.
The practical question is therefore not how to send more requests, but which discovery and crawling signals are appropriate for the page you have published.
What the Google Indexing API currently supports
| Item | Confirmed detail | Practical meaning |
|---|---|---|
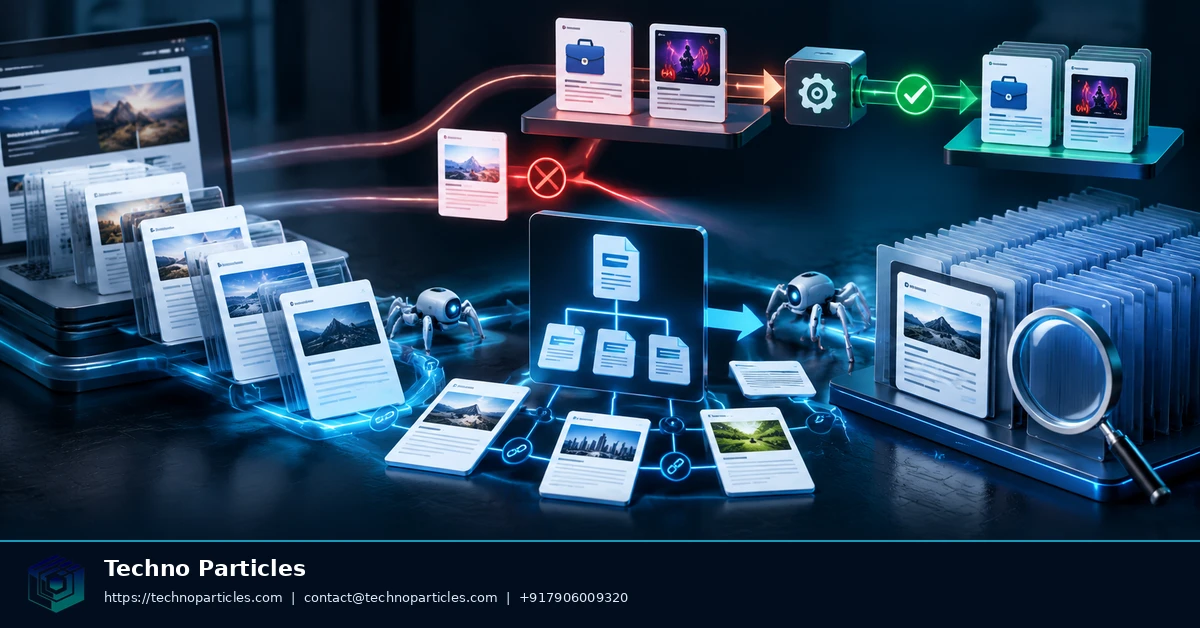
| Eligible content | JobPosting pages and livestreaming video pages using BroadcastEvent in VideoObject | Ordinary pages should use standard Google Search workflows |
| Daily publish quota | 200 requests per project | A quota does not override eligibility rules |
| API result | Notifications about updates or deletions | Submission does not guarantee crawling or indexing |
| Current documentation | Quota page revised October 16, 2026 | An outdated approval form was removed |
Why ordinary pages need a different route
For a new article or landing page, begin with a technically accessible URL and a useful reason for Google to revisit it. Add the page to an accurate XML sitemap, connect it through crawlable internal links, and check that robots.txt, server responses and canonical signals do not block discovery.
For a small number of important URLs, Google recommends the Search Console URL Inspection tool. Larger publishing operations should maintain sitemap coverage and a consistent internal-link structure. Google notes that recrawling can take days to weeks, and repeated requests do not make crawling happen faster.
Teams planning a broader SEO workflow should also separate four stages: discovery, crawling, indexing and ranking. A successful submission or inspection request addresses only part of that chain; it cannot substitute for accessible, valuable and indexable content.
How to improve discovery without misusing the API
Start by confirming that the page can be reached without authentication, excessive client-side rendering or accidental blocking. Test the live URL, review its HTTP response, and check whether robots.txt permits crawling. The page should also use a clear canonical URL and avoid conflicting signals from redirects, duplicate versions or noindex directives.
Next, make the page easy to find within the site itself. Link to it from relevant, already discoverable pages using descriptive anchor text. For a new article, that might mean connecting it from a topic hub, category page or related guide. For a product or service page, links from navigation, comparison content and supporting resources can create a more logical crawl path. An experienced website development workflow can help teams address these structural details before publication.
A practical publishing checklist
- Inspect priority URLs: Use Search Console’s URL Inspection tool when only a small number of pages need attention.
- Maintain the sitemap: Include canonical, indexable URLs and remove pages that are permanently unavailable or intentionally excluded.
- Strengthen internal links: Place new pages within relevant sections rather than leaving them accessible only through a sitemap.
- Review content quality: Make sure the page provides original, useful information instead of thin variations created solely to attract crawling.
- Monitor technical signals: Check server availability, mobile rendering, redirects, canonical tags and indexing reports over time.
These steps improve the conditions Google uses to discover and evaluate ordinary pages, but they do not create an instant indexing guarantee. Google’s guidance says recrawling may take days to weeks, while crawling itself remains separate from indexing and ranking. A page can be crawled yet excluded from the index, or indexed without gaining meaningful visibility. That distinction is especially important when publishing at scale: automation can keep sitemaps and links consistent, but it cannot replace editorial value or technical validation.
What to monitor after publication
Once the technical basics are in place, monitor each page through the appropriate Search Console reports rather than repeatedly resubmitting it. URL Inspection can show whether Google has discovered a URL, whether crawling is allowed and whether an indexed version exists. Those signals answer different questions, so an “URL is not on Google” result should lead to diagnosis, not automatic API use.
Review the page’s canonical selection, indexability and rendered content. A page may be reachable but still unsuitable for indexing because it duplicates another URL, contains a noindex directive or offers too little distinct value. Google’s guidance also separates crawling from ranking: even after a page enters the index, search visibility depends on relevance, quality and competition.
Use automation for consistency, not artificial urgency
Publishing systems can make the standard workflow more reliable. They can generate accurate sitemap entries, update last-modified values when content materially changes, validate canonical URLs and identify broken internal links. They can also alert teams when a new page returns an unexpected status code or becomes blocked by robots.txt. A structured CMS implementation can support these checks without treating Google’s Indexing API as a universal notification tool.
Before using the API, confirm that the page genuinely contains one of Google’s documented eligible features: a job posting or a livestreaming video represented with the required structured data. A successful request outside those supported cases should not be interpreted as evidence that the page qualifies or will be indexed.
Questions to ask before requesting faster discovery
- Is the URL canonical, indexable and accessible to Googlebot?
- Does an XML sitemap contain the correct version of the page?
- Can users and crawlers reach it through relevant internal links?
- Has the page changed substantially enough to justify recrawl attention?
- Am I measuring discovery, indexing or ranking as the actual outcome?
This process helps publishers focus effort where it can produce a measurable technical improvement while respecting Google’s documented API scope and normal recrawl timelines.
What the quota update does—and does not—change
Google’s October 16, 2026 documentation update clarified the current Indexing API quota page, but it did not turn the API into a general-purpose submission channel. The published free-service limits are 200 publish requests per project per day, 180 metadata requests per project per minute and 380 total requests per project per minute. These are request limits, not promises that Google will crawl or index a URL.
That distinction matters for ordinary new pages. A blog article, service page, product detail or ecommerce category does not become eligible merely because an application can authenticate successfully or receive a successful API response. Google’s documented scope remains focused on pages containing JobPosting or BroadcastEvent information within VideoObject markup. Using the endpoint for unrelated pages can create misleading operational signals: the system may report that a request was accepted, while the page still follows Google’s normal discovery, crawling and indexing processes.
Choose the workflow that matches the page
| Page situation | Appropriate action | What to expect |
|---|---|---|
| A few ordinary URLs | Inspect them in Search Console | A request for consideration, not instant indexing |
| Many ordinary URLs | Update the XML sitemap and internal links | Discovery and recrawl on Google’s schedule |
| Eligible job or livestream pages | Use the Indexing API within its documented scope | Faster notification of changes, without an indexing guarantee |
Teams can reduce avoidable delays by making these signals consistent before publishing. A technical SEO review can help identify blocked resources, conflicting canonicals, weak navigation paths and sitemap errors, although no service can guarantee a particular crawl or ranking outcome.
For larger publishing operations, record the publication time, canonical URL, sitemap status, HTTP response and Search Console inspection result for each priority page. This creates a useful audit trail and helps separate a technical failure from Google’s ordinary processing time.
How to turn monitoring into faster diagnosis
An audit trail becomes most useful when it connects each URL to a specific failure mode. If a page returns a server error, resolve availability before inspecting indexing status. If Googlebot is blocked, review robots.txt, firewall rules and authentication requirements. If the URL is crawled but excluded, examine canonical signals, duplicate content and the page’s distinct value.
For a small number of priority pages, use Search Console’s URL Inspection tool after confirming that the live URL is accessible. Submit only the canonical version and check whether the rendered page contains the important text and structured data. A successful inspection request is still a request for recrawling, not a guarantee that Google will index the page.
Build a dependable publishing checklist
- Return a stable, successful HTTP response for the canonical URL.
- Keep important content available without requiring blocked scripts or login access.
- Add new pages to an accurate XML sitemap when they become eligible for discovery.
- Link to them from relevant, crawlable pages using descriptive navigation.
- Check for accidental noindex directives, conflicting canonicals and redirect chains.
For high-volume sites, these checks can run during deployment. A CMS implementation can validate sitemap entries, canonical tags and link paths before a page is published. That kind of automation reduces preventable delays, but it does not change Google’s crawl scheduling or convert ordinary pages into Indexing API targets.
Why repeated requests are not a speed strategy
Google’s recrawl guidance says crawling can take days to weeks, and repeated requests do not make the process faster. Most new pages should not be expected to receive same-day crawling. If a page remains undiscovered, improve its technical accessibility and prominence rather than sending the same notification repeatedly.
Also separate indexing from ranking. A page can be crawled and stored while remaining difficult to find because its content is weakly differentiated, poorly aligned with search intent or competing against stronger results. Review those quality signals only after confirming that discovery and indexability are functioning.
Google Indexing API limitation: the practical conclusion
The fastest way to index ordinary new pages is not to repeat unsupported API requests. It is to remove obstacles from Google’s normal discovery and crawling systems, then give the search engine clear signals about which URLs matter. The Indexing API remains a specialised notification mechanism for eligible job and livestream pages, not a general accelerator for blog posts, service pages, product pages or ecommerce categories.
For most sites, start with the basics: publish a stable canonical URL, include it in an accurate XML sitemap, connect it through relevant internal links and confirm that robots.txt, server responses and page directives allow access. Use Search Console’s URL Inspection tool for a small number of important pages, but treat the request as an invitation to recrawl rather than an indexing command.
Measure the right outcome
Track discovery, crawling, indexing and ranking as separate stages. A URL may be discovered but not crawled, crawled but excluded, or indexed without performing well for its intended query. This distinction prevents teams from misdiagnosing a content or relevance problem as an API problem. It also makes reporting more honest: a successful submission does not prove that a page is indexed or visible in search results.
Google’s documented guidance allows for delays ranging from days to weeks, and repeated recrawl requests do not shorten that schedule.
Leave a comment
Your email stays private. You can see your comment immediately on this browser. Others see it after approval.