
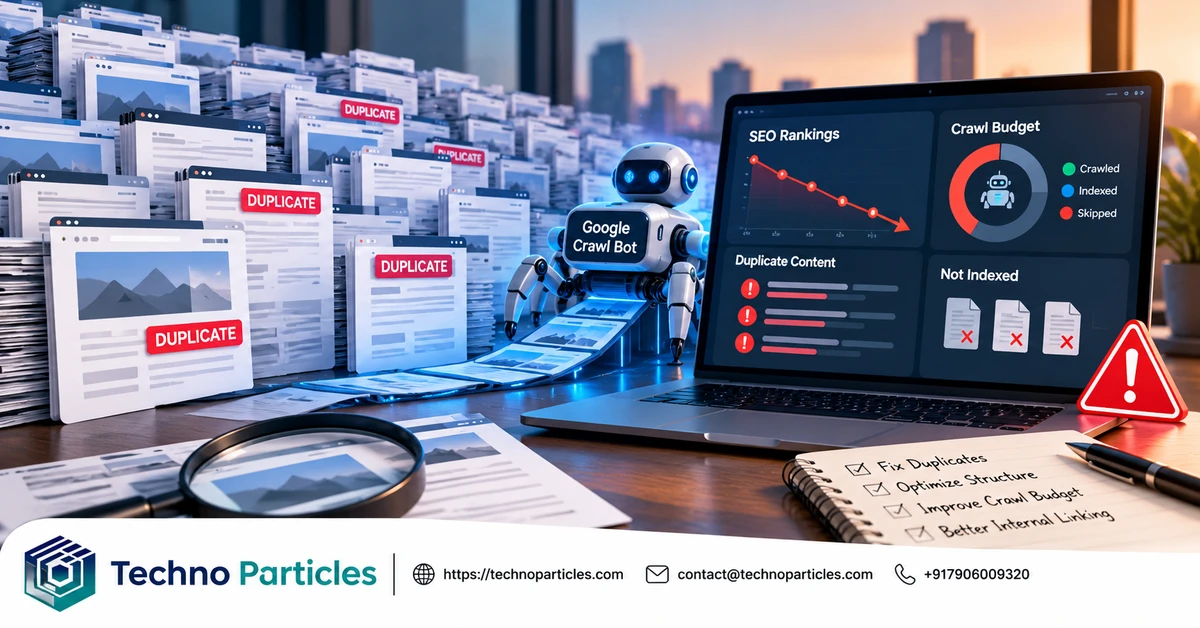
Can too many website pages hurt SEO rankings? Not simply because a site has a high page count. Google’s guidance points instead to the quality, uniqueness, and crawlability of those URLs. A large website can perform well when its pages serve distinct user needs, while a smaller site can create problems through duplicate pages, uncontrolled filters, or thin content.
| Page issue | Potential SEO impact | Practical response |
|---|---|---|
| Duplicate or near-duplicate URLs | Crawl resources may be wasted and signals may be consolidated | Use canonical URLs, redirects, and consistent internal links |
| Faceted navigation combinations | Filter URLs can create an effectively huge crawl space | Control crawl paths and keep preferred pages discoverable |
| Thin, unoriginal pages | Pages may provide little value and create broader quality concerns | Improve, consolidate, or remove pages that serve no clear purpose |
Why page volume alone is not a ranking penalty
Google does not publish a universal page-count threshold at which rankings decline. Crawl-budget concerns are most relevant to very large or frequently changing websites, not automatically to every business site. The more important question is whether search engines can efficiently discover and understand the pages that matter.
When several URLs show substantially the same content, Google may group them and select a canonical version. Duplicate alternatives are typically crawled less often, which can delay the discovery of important updates. However, a canonical tag is a signal rather than an absolute command. Redirects, sitemap inclusion, internal linking, and page-level content all help reinforce the preferred URL.
Where too many pages become a real SEO risk
Problems often begin with tracking parameters, session IDs, endless filter combinations, automatically generated archives, or overlapping location and service pages. These URLs can expand the crawl space without adding meaningful search value. A focused SEO audit and technical review can help separate useful indexable pages from duplicates and low-value variants.
How duplicate content and crawl budget interact
Duplicate content does not usually trigger an automatic ranking penalty, but it can make a site’s signals less clear. If product, service, or archive pages repeat the same material at different URLs, Google must decide which version represents the main result. The alternatives may still exist, yet they are less useful as independent landing pages and may receive less crawling attention.
Crawl budget describes the resources Google allocates to discovering and processing a site’s URLs. Google’s crawl-budget guidance focuses mainly on very large or rapidly changing sites, but the underlying principle applies broadly: make important pages easy to find and avoid generating unnecessary URL variations. A site with thousands of legitimate pages is not automatically problematic; a site with thousands of near-identical filter combinations may be.
What site owners should check first
- Compare indexed and discovered URLs: Use Search Console coverage and indexing reports to identify duplicates, alternate versions, and pages that Google has not selected for indexing.
- Inspect parameters and filters: Look for sorting, tracking, session, and faceted-navigation URLs that create no distinct search experience.
- Consolidate overlapping pages: Where two pages target the same intent, combine their strongest information into one useful URL instead of maintaining thin variations.
- Reinforce the preferred version: Use redirects when a page should permanently resolve elsewhere, canonical tags for suitable duplicate relationships, consistent internal links, and XML sitemaps containing preferred indexable URLs.
Apply noindex selectively to pages that should remain accessible but should not appear in search. Blocking crawling alone can prevent Google from seeing canonical signals, so it is not a universal substitute for consolidation. For sites with complex templates or large inventories, a technical project consultation can help map URL patterns before changes are deployed.
Quality matters more than the raw page count
Pages created mainly to capture search traffic, without original usefulness or a clear audience need, create a broader quality risk. The strongest architecture keeps each indexable page distinct, purposeful, internally connected, and supported by content that answers a real query.
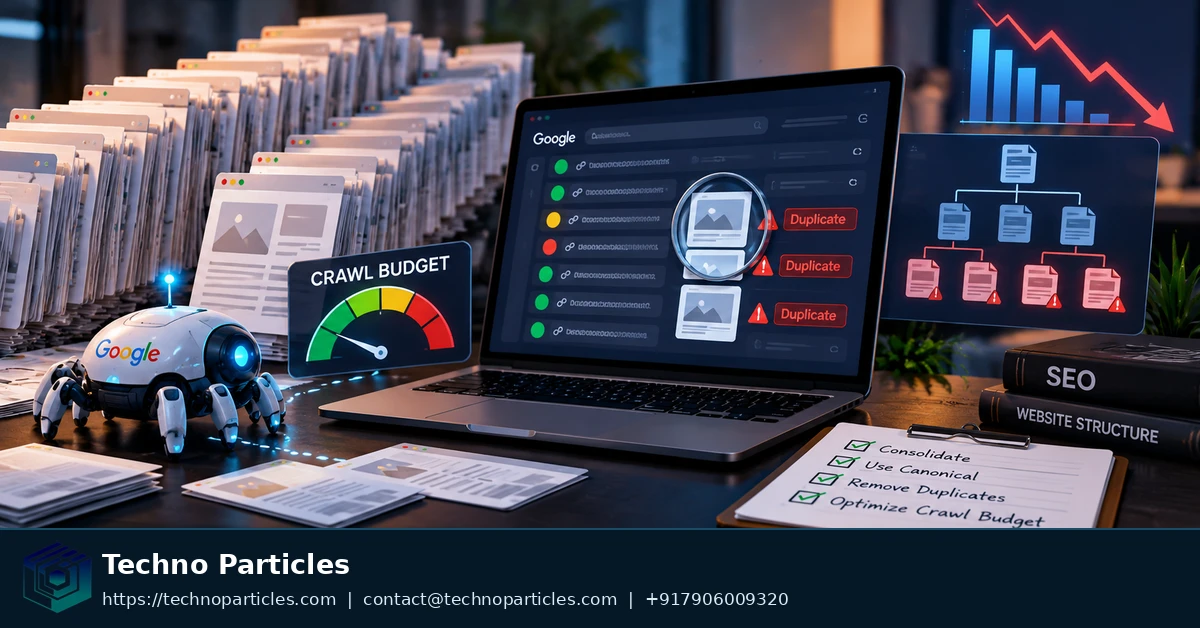
How to distinguish useful expansion from SEO bloat
Adding pages can support organic visibility when each URL addresses a distinct need. For example, separate product pages, documentation pages, or location pages may be appropriate when they contain genuinely differentiated information. The problem is not expansion itself; it is publishing variants that add little beyond a changed keyword, parameter, or template field.
Google’s people-first content guidance is useful here. Before keeping a page indexable, ask whether a visitor would find it valuable as a standalone destination. Does it answer a specific question, provide original detail, support a real task, or help users make a decision? If the answer is unclear, the page may be better consolidated with a stronger resource.
A practical audit sequence for large URL sets
- Group URLs by intent: Export indexable, indexed, and discovered URLs, then cluster pages that target the same query or customer need.
- Compare the actual content: Check titles, headings, main copy, structured data, and visible information rather than relying only on URL patterns.
- Review crawl signals: Look for repeated parameter URLs, redirect chains, soft errors, orphan pages, and internal links that point to alternate versions.
- Set a clear action: Keep distinct pages, merge overlapping pages, redirect retired URLs, or apply
noindexwhere exclusion is intentional.
After changes, monitor indexing reports and server activity instead of expecting an immediate ranking shift. Search Console can reveal whether Google is selecting the preferred canonical, while log analysis can show whether crawlers repeatedly request low-value URL patterns. A focused technical SEO service can help interpret those signals when a site has complex templates or a large catalogue.
Why faceted navigation deserves special attention
Filters for colour, price, size, brand, or sorting can generate thousands of combinations. Some combinations may deserve landing pages, but most should not become independent search targets. Define which filtered states have unique demand and content, then control the rest through linking, canonicalisation, or other documented crawl-management choices. This keeps the site’s important page set understandable as it grows.
Faceted navigation deserves special attention because filters for colour, price, size, brand, or sorting can generate thousands of URL combinations. Some combinations may deserve dedicated landing pages, but most should not become independent search targets. Define which filtered states have unique demand and useful content, then control the rest through consistent internal linking, canonicalisation, or other documented crawl-management choices.
When a page should stay, merge, or disappear
A practical decision depends on user value and search intent. Keep a page when it serves a distinct audience need and contains information that cannot be found on a stronger parent page. Merge pages when they repeat the same answer, differ only by minor wording, or divide links and maintenance effort without adding useful detail. Redirect retired URLs when another page fully replaces them.
Use noindex for accessible pages that have a legitimate functional purpose but should not appear in search, such as certain internal results or temporary variations. Do not treat it as a cure for every duplicate: the page still consumes resources if Google must crawl it, and blocking access can prevent crawlers from seeing consolidation signals.
What to monitor after cleanup
- Canonical selection: Check whether Google recognises the preferred URL rather than an alternate duplicate.
- Indexing patterns: Review whether important pages move from discovered or crawled-but-not-indexed states into the index.
- Crawl activity: Watch server logs or crawl reports for repeated requests to parameters, filters, redirects, or obsolete paths.
- Organic performance: Compare impressions and clicks for consolidated pages over a reasonable monitoring period.
For complex ecommerce, CMS, or application builds, URL rules should be defined before templates generate thousands of pages. A focused technical SEO service can help connect sitemap design, internal links, canonical tags, and faceted-navigation controls into one maintainable system.
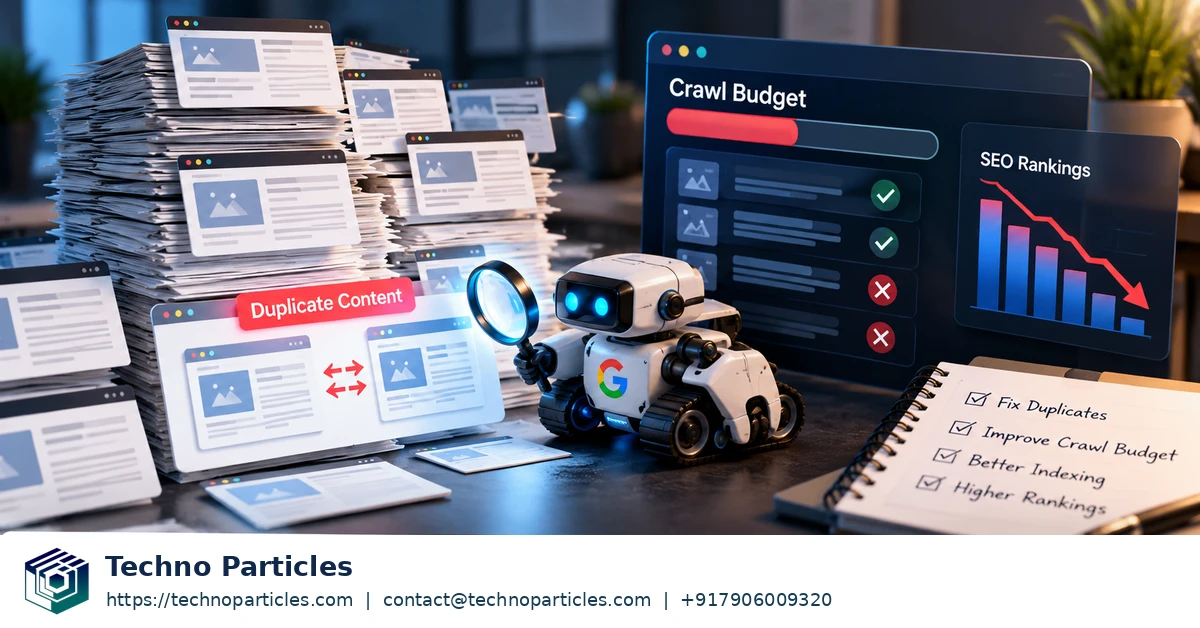
Can too many website pages hurt SEO rankings?
Too many website pages can hurt SEO indirectly when they create duplication, dilute internal signals, or consume crawling resources that should support important URLs. Google does not publish a universal page-count threshold, so the right question is not how many pages a site has, but whether its indexable pages are useful, distinct, and technically controlled.
Build a cleaner page system
Start by defining the preferred URL for every important topic, product, service, or category. Use consistent internal links, include preferred indexable URLs in the XML sitemap, and apply rel="canonical" when equivalent versions must remain accessible. If an old URL has a clear replacement, a redirect is usually more appropriate. These signals help Google understand consolidation, but they are not absolute commands; the page content, redirects, links, and sitemap should all support the same choice.
For parameter and filter URLs, decide which combinations have genuine search value before allowing them to become landing pages. A page targeting a specific product type may deserve unique copy and navigation, while a URL created only by sorting or selecting an incidental filter usually adds little value. Review templates so they do not automatically generate indexable pages with nearly identical titles, descriptions, and body content.
Use Search Console to find the real problem
Search Console can help separate a large but healthy site from one with SEO bloat. Compare indexed pages with discovered-but-not-indexed and crawled-but-not-indexed URLs. Inspect representative duplicates to see which canonical Google selected, then examine internal links and sitemap entries for conflicting signals. Server logs can add another layer by showing whether bots repeatedly request parameters, redirect chains, or obsolete paths.
For a complex CMS or ecommerce site, a focused technical SEO service can help turn these findings into maintainable URL, sitemap, and template rules.
Turn the audit into a controlled page system
Once duplicate and low-value URLs are identified, prioritise the pages that deserve search visibility. Keep pages that serve distinct user intent and provide information unavailable elsewhere. Merge overlapping pages when they answer the same question or split authority without adding meaningful value. Redirect retired URLs when a clear replacement exists, and use noindex for accessible utility pages that have a legitimate purpose but should not appear in search.
Do not rely on one technical signal in isolation. The preferred URL should be supported by consistent internal links, relevant redirects, accurate canonical tags, and an XML sitemap containing only indexable URLs. Google treats these as signals rather than absolute commands, so the page content and site structure must also make the intended choice clear.
Monitor whether cleanup improves visibility
After changes, use Search Console to compare indexed pages with discovered-but-not-indexed and crawled-but-not-indexed URLs. Inspect representative duplicates to see whether Google selected the intended canonical. Server logs can reveal repeated crawling of parameters, filter combinations, redirect chains, or obsolete paths that standard reports may not fully explain.
Track impressions, clicks, and indexing patterns for important consolidated pages over a reasonable period. A temporary change in traffic does not automatically prove that a cleanup succeeded or failed; evaluate whether the site is becoming easier to crawl and whether priority pages are receiving clearer signals.
Leave a comment
Your email stays private. You can see your comment immediately on this browser. Others see it after approval.