
OpenAI announced GPT-6 Cyber on November 5, 2026, positioning it for authorized vulnerability discovery, exploit development, security testing, and fix validation. The GPT-6-Cyber API setup therefore involves more than creating a model key: teams need approved access, defined targets, controlled tools, and reviewable evidence.
| Area | Verified detail | Practical meaning |
|---|---|---|
| Model | gpt-6-cyber through the Responses API | Use the approved model ID and supported API workflow. |
| Access | Daybreak Red approval plus separate GPT-6 Cyber approval | Eligibility depends on organization and project approval. |
| Context | 1,050,000-token context window and 128,000-token maximum output | Large codebases and test evidence can fit in staged workflows. |
| Safety | Cybersecurity monitoring can return cyber_policy | Applications need retry, review, and fail-closed handling. |
What changed with GPT-6 Cyber?
OpenAI’s announcement describes GPT-6 Cyber as an agent for defensive and authorized security work, including penetration testing, red teaming, exploit validation, patch validation, and secure software-development workflows. Access is tied to the Daybreak Red program, which is intended for approved internal use. A broader application project may also require clear scope planning through project consultation support.
OpenAI reports 48.5% on ExploitGym, compared with 32.1% for GPT-5.6 Cyber, and 40.3% web-pentesting vulnerability recall versus 32.0% for GPT-6 Astra. The company also reports 99.93% avoidance of out-of-scope services without deployment safety prompts. These figures are OpenAI-reported evaluations, not universal guarantees of real-world performance. The GPT-6 Cyber System Card classifies the model as Critical in cybersecurity under OpenAI’s Preparedness Framework.
OpenAI also says GPT-6 Cyber helped identify 81 previously unknown high-severity Firefox vulnerabilities and develop working exploits for 948 Linux kernel vulnerabilities. Those results show why the model may assist expert teams, but they do not grant permission to test systems outside an approved scope. The next step is an access-controlled API workflow built around explicit authorization.
GPT-6-Cyber API setup for authorized vulnerability testing and fix verification
GPT-6-Cyber access starts with two approvals. OpenAI’s Daybreak overview says organizations need Daybreak Red access and separate approval for GPT-6 Cyber. The approved organization, project, and API key must match that authorization. This is an eligibility control, not a normal model-switching step. OpenAI’s Daybreak guidance also describes internal-use restrictions, explicit authorization, IP allowlisting, and project configuration.
Before sending a request, create a target inventory. List owned systems, approved addresses, test windows, permitted techniques, data boundaries, and an owner who can stop the test. Keep third-party assets out unless written authorization covers them. Teams can map these owners and review gates through requirements-discovery consultation.
Use the documented model ID, gpt-6-cyber, with the Responses API after approval. The official model page lists a 1,050,000-token context window and a 128,000-token maximum output. Large repositories and evidence sets should still be split into stages: discovery, reproduction, remediation review, and final verification. Staging makes permissions and audit records easier to inspect. OpenAI’s GPT-6-Cyber model documentation describes the supported API configuration and model limits.
Store keys in a controlled secret manager. Restrict outbound network access to approved targets. Give tools the smallest permissions needed for the current stage. Require a human decision before exploit execution, destructive changes, credential use, or any action whose target is unclear. Record prompts, tool calls, approvals, returned findings, and fix-validation evidence. If approval or scope checks fail, stop the workflow instead of continuing with a broader request.
The approval chain before the first request
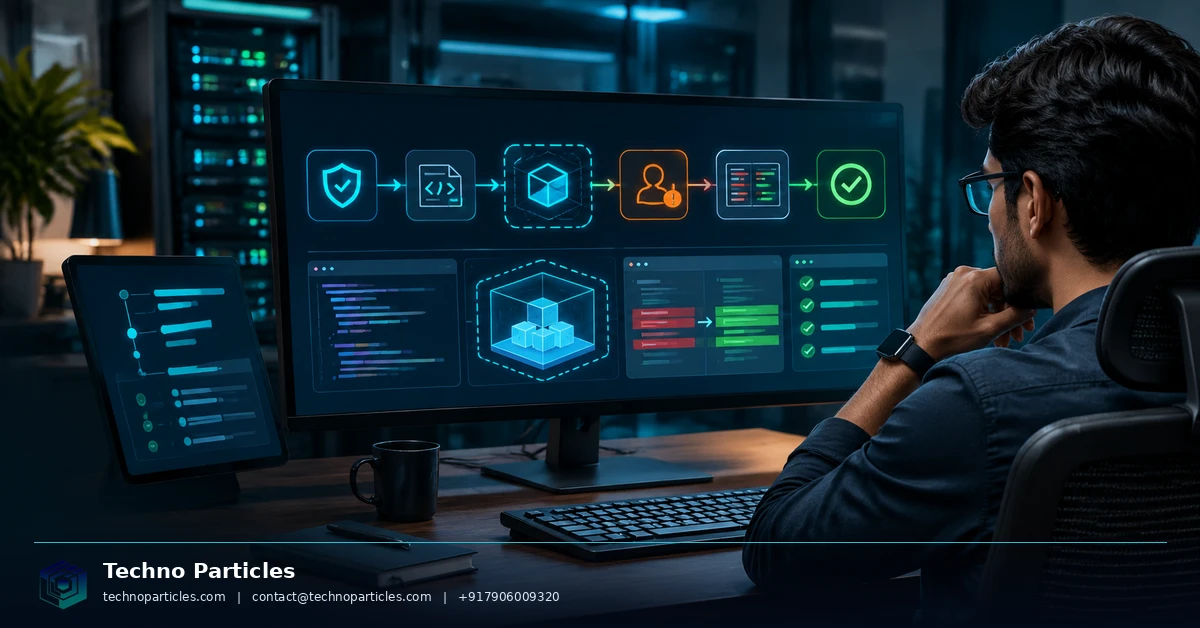
The access path has separate gates. OpenAI’s Daybreak overview, updated November 6, 2026, distinguishes Daybreak access levels and states that GPT-6 Cyber requires Daybreak Red access plus separate approval for the model. Treat both approvals as prerequisites before designing an automated testing job. A successful API response from another model does not demonstrate that the organization, project, or key is eligible for gpt-6-cyber. The Daybreak access guidance also describes internal-use restrictions and explicit authorization requirements.
After approval, confirm that the API organization and project selected by the application match the approved security program. Use an approved key for that project, apply the required IP allowlist, and bind requests to an authenticated service identity. Keep model access separate from target authorization: the approval permits use of the service under its controls, while the test owner must still document permission for every system, address range, and testing window.
Configure the project around the test boundary
Create one project or execution boundary for the authorized assessment, with a target inventory and an owner responsible for stopping activity. Record the permitted network ranges, excluded assets, data-handling rules, tool permissions, and escalation contacts before enabling automated calls. If the workflow supports multiple clients or environments, separate them by project or equivalent policy boundary so credentials, logs, and findings cannot cross contexts.
The model page identifies gpt-6-cyber as the API model and documents Responses API support. It also lists a 1,050,000-token context window and a 128,000-token maximum output, but those limits do not remove the need to stage requests. Send discovery findings first, then submit only the approved evidence needed for reproduction or remediation review. Keep sensitive values out of prompts unless the approved workflow specifically requires them, and redact secrets from retained logs. OpenAI’s model documentation defines the supported configuration and limits.
Teams planning an application around this controlled integration can document the workflow through AI integration services, while retaining authorization and security decisions with the responsible testing team.
Turn approval into a controlled API path
Approval becomes useful only when the application enforces it at request time. Bind the integration to the approved organization and project, then reject requests that select another project, environment, or model. Keep the approved key available only to the service that runs the assessment. Do not expose it to analysts’ browsers, notebooks, or client-side application code.
Represent authorization as deployment data. Store the assessment identifier, target ranges, permitted test window, excluded assets, data rules, and approving owner beside the job configuration. The request runner should load that record before invoking gpt-6-cyber. If the record is missing, expired, or inconsistent with the selected project, fail closed.
Separate model configuration from tool configuration. The model can analyze supplied evidence, but scanners, shells, browsers, repositories, and network clients need independent allowlists. Grant each tool only the permissions required for its current stage. A discovery job may read approved hosts, while reproduction or patch validation may require a different review gate. OpenAI’s cybersecurity checks guidance recommends reviewing sensitive tool calls, denying unauthorized actions, and requiring human approval for ambiguous or high-risk changes.
Make the first deployment small. Use one isolated project, one test environment, one service identity, and a narrow target inventory. Confirm that logs capture the request owner, model, tool call, target, approval decision, returned finding, and follow-up action. This creates an auditable path before teams add parallel assessments or broader automation.
For teams planning the surrounding workflow, AI integration planning services can help document system boundaries and handoffs. Authorization, target ownership, and security approval must remain with the responsible testing organization.
Build the vulnerability test as staged work
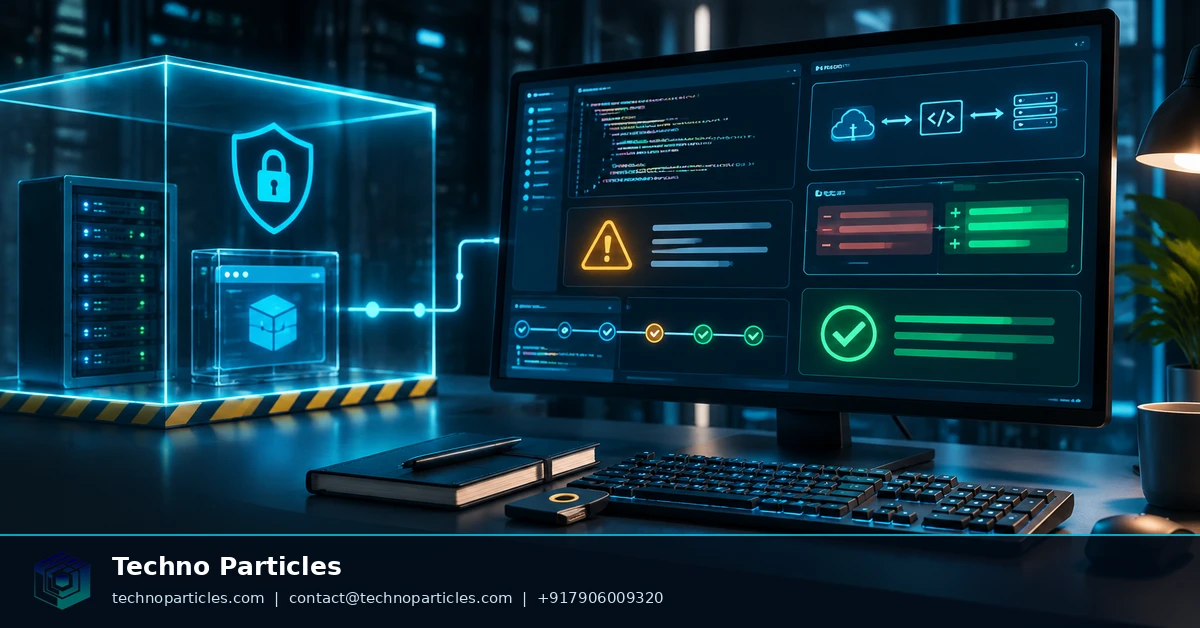
Start with a written rules-of-engagement record. Name every approved asset, address range, repository, application, testing window, excluded system, permitted technique, data rule, and escalation contact. Assign one owner who can stop the job. OpenAI’s cybersecurity checks guidance recommends reviewing sensitive actions against approved scope and denying unauthorized requests.
Separate discovery, reproduction, and remediation review
Use separate workflow stages instead of granting every tool full access at once. Discovery can collect evidence from approved targets. Reproduction can test one documented finding inside the permitted boundary. Remediation review can compare the same finding against a patched test environment. Give each stage its own tool allowlist and approval state.
Require a human decision before actions that can alter systems, access sensitive data, widen the target set, or create durable changes. The reviewer should see the proposed action, target, expected effect, authorization record, and rollback plan. If review is unavailable or the request is ambiguous, pause the action. OpenAI’s guidance calls for human approval of ambiguous or high-risk tool calls and independent network and filesystem boundaries.
Capture evidence as an assessment record, not as loose chat history. Store the assessment ID, request owner, selected project, model, target, tool call, approval result, timestamps, returned evidence, and analyst disposition. Keep discovery output separate from secrets, credentials, and unrelated customer data. A project consultation workflow can help map these handoffs before implementation, but the testing owner must approve the final controls.
Run the first assessment against one isolated environment and a narrow target list. Confirm that excluded assets remain untouched, denied actions stop, and every approved action leaves an audit entry. Expand scope only after the control path works under review.
When GPT-6-Cyber API setup is the right choice
Use GPT-6-Cyber API setup for authorized vulnerability testing and fix verification only when four conditions are true: your organization has approved access, the assessment has explicit authorization, testing runs inside isolated infrastructure, and a qualified human can review high-risk actions. This is the decision rule. If one condition is missing, do not activate the workflow for live testing. Use a lower-risk defensive workflow while the responsible team requests access or closes the control gap.
Approval does not replace operational ownership. The testing team still decides which assets belong in scope, what evidence may be collected, which actions require review, and when the assessment must stop. Keep that decision outside the model. The API should enforce the approved project, service identity, target boundary, and tool permissions before work begins.
Next, create one readiness record for the first assessment. Name the approved project, target environment, testing window, responsible owner, excluded assets, review points, and evidence location. Then run one narrow validation job in the isolated environment. Confirm that the request uses the approved model, denied actions remain blocked, reviewers can pause risky steps, and the resulting evidence supports a human decision. Expand scope only after that control path works end to end.
This approach makes GPT-6-Cyber API setup a controlled security capability instead of an unrestricted automation layer. It also gives the team a clear stop condition: no authorization, no isolation, or no human review means no live vulnerability test.
Leave a comment
Your email stays private. You can see your comment immediately on this browser. Others see it after approval.